Nemotron
NVIDIA Trains Nemotron Speech Model on Saudi Audio Dataset to Cut Transcription Errors
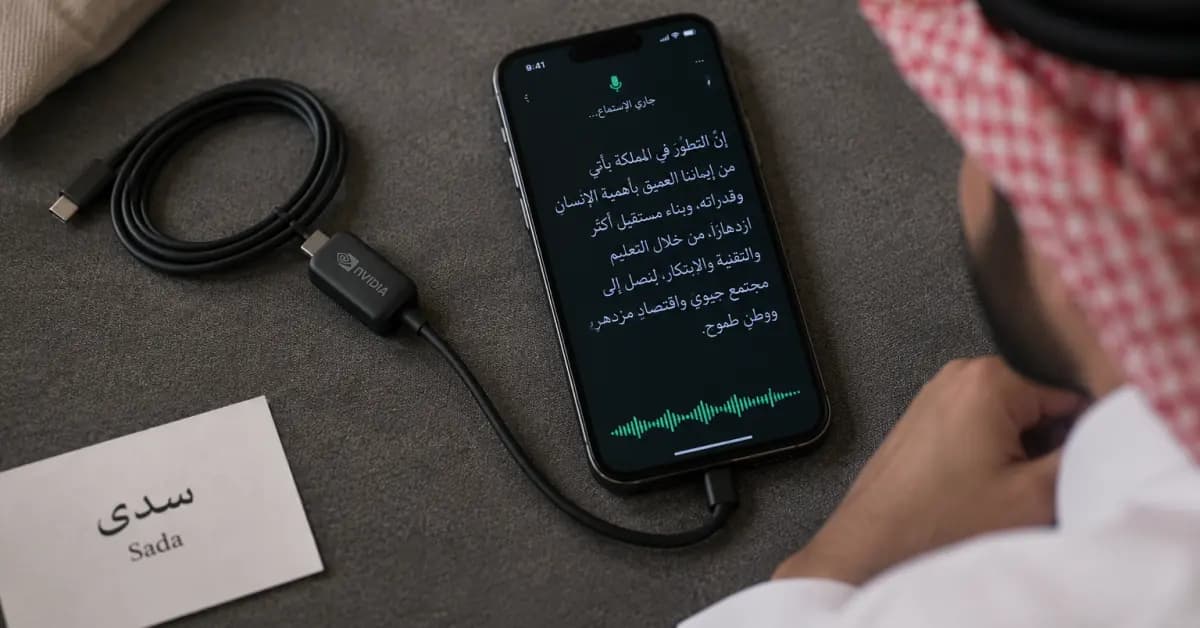
NVIDIA used SDAIA’s Sada dataset to train its Nemotron 3.5 speech model, cutting Saudi dialect transcription error rates nearly in half.
SSICT News ·
NVIDIA used SDAIA’s Sada dataset to train its Nemotron 3.5 speech model, cutting Saudi dialect transcription error rates nearly in half.
SSICT News ·