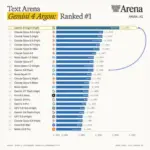
Gemini 4 Argon has secured first place on the APEX-Agents benchmark after achieving an 82.2 percent Pass@1 score. The result establishes the system as the first artificial intelligence model to surpass the 80 percent threshold on this specialized agent evaluation framework.
Benchmark Results on APEX-Agents
According to evaluation data shared by Mercor, the performance score places the model ahead of competing systems across agentic tasks. Specifically, the evaluation showed that Gemini 4 Argon outperformed Sonnet 5.5 by a margin of 6.7 points on the Pass@1 metric.
The APEX-Agents benchmark measures the autonomous execution capabilities of models across complex environments. Achieving an 82.2 percent score indicates high task completion accuracy on primary attempts within artificial intelligence agent workflows.
Understanding Pass@1 and Agentic Metrics
In artificial intelligence benchmarking, Pass@1 serves as an essential indicator of operational reliability and efficiency. This metric measures whether an agent can successfully complete a given assignment on its initial attempt without requiring iterative guidance, multiple trial runs, or error-correction loops.
In practical operational deployments, higher Pass@1 execution rates reduce latency and lower computational overhead. When an autonomous system completes tasks correctly on the first attempt, it minimizes the necessity for human supervision and repetitive re-prompting cycles.
Evaluation and Performance Findings
Mercor published the comparative rankings, which were highlighted by Aligned News. By exceeding the previous standard set by Sonnet 5.5, Gemini 4 Argon demonstrates measurable gains in independent decision-making tests across structured environments.
The benchmark test evaluates how software agents interpret instructions, call tools, and solve multi-step operational problems. Furthermore, reaching this milestone reflects ongoing architectural advancements in computing systems designed for high-reasoning tasks.
Impact on Autonomous Systems
Specialized agent metrics such as APEX-Agents focus strictly on tool utilization, function execution, and multi-step task completion rather than standard text output. Consequently, high scores on these tests provide insight into model reliability for enterprise workflows and automated apps development.
Future Outlook
Industry benchmarks continue to track agent performance as software developers deploy systems for automated operations. The 82.2 percent Pass@1 benchmark score established by Gemini 4 Argon provides a new performance reference point for future agentic model evaluations.